
 FrontiersMind
Blog
From the Lab
How we build efficient models, what we measured, and how to run them.
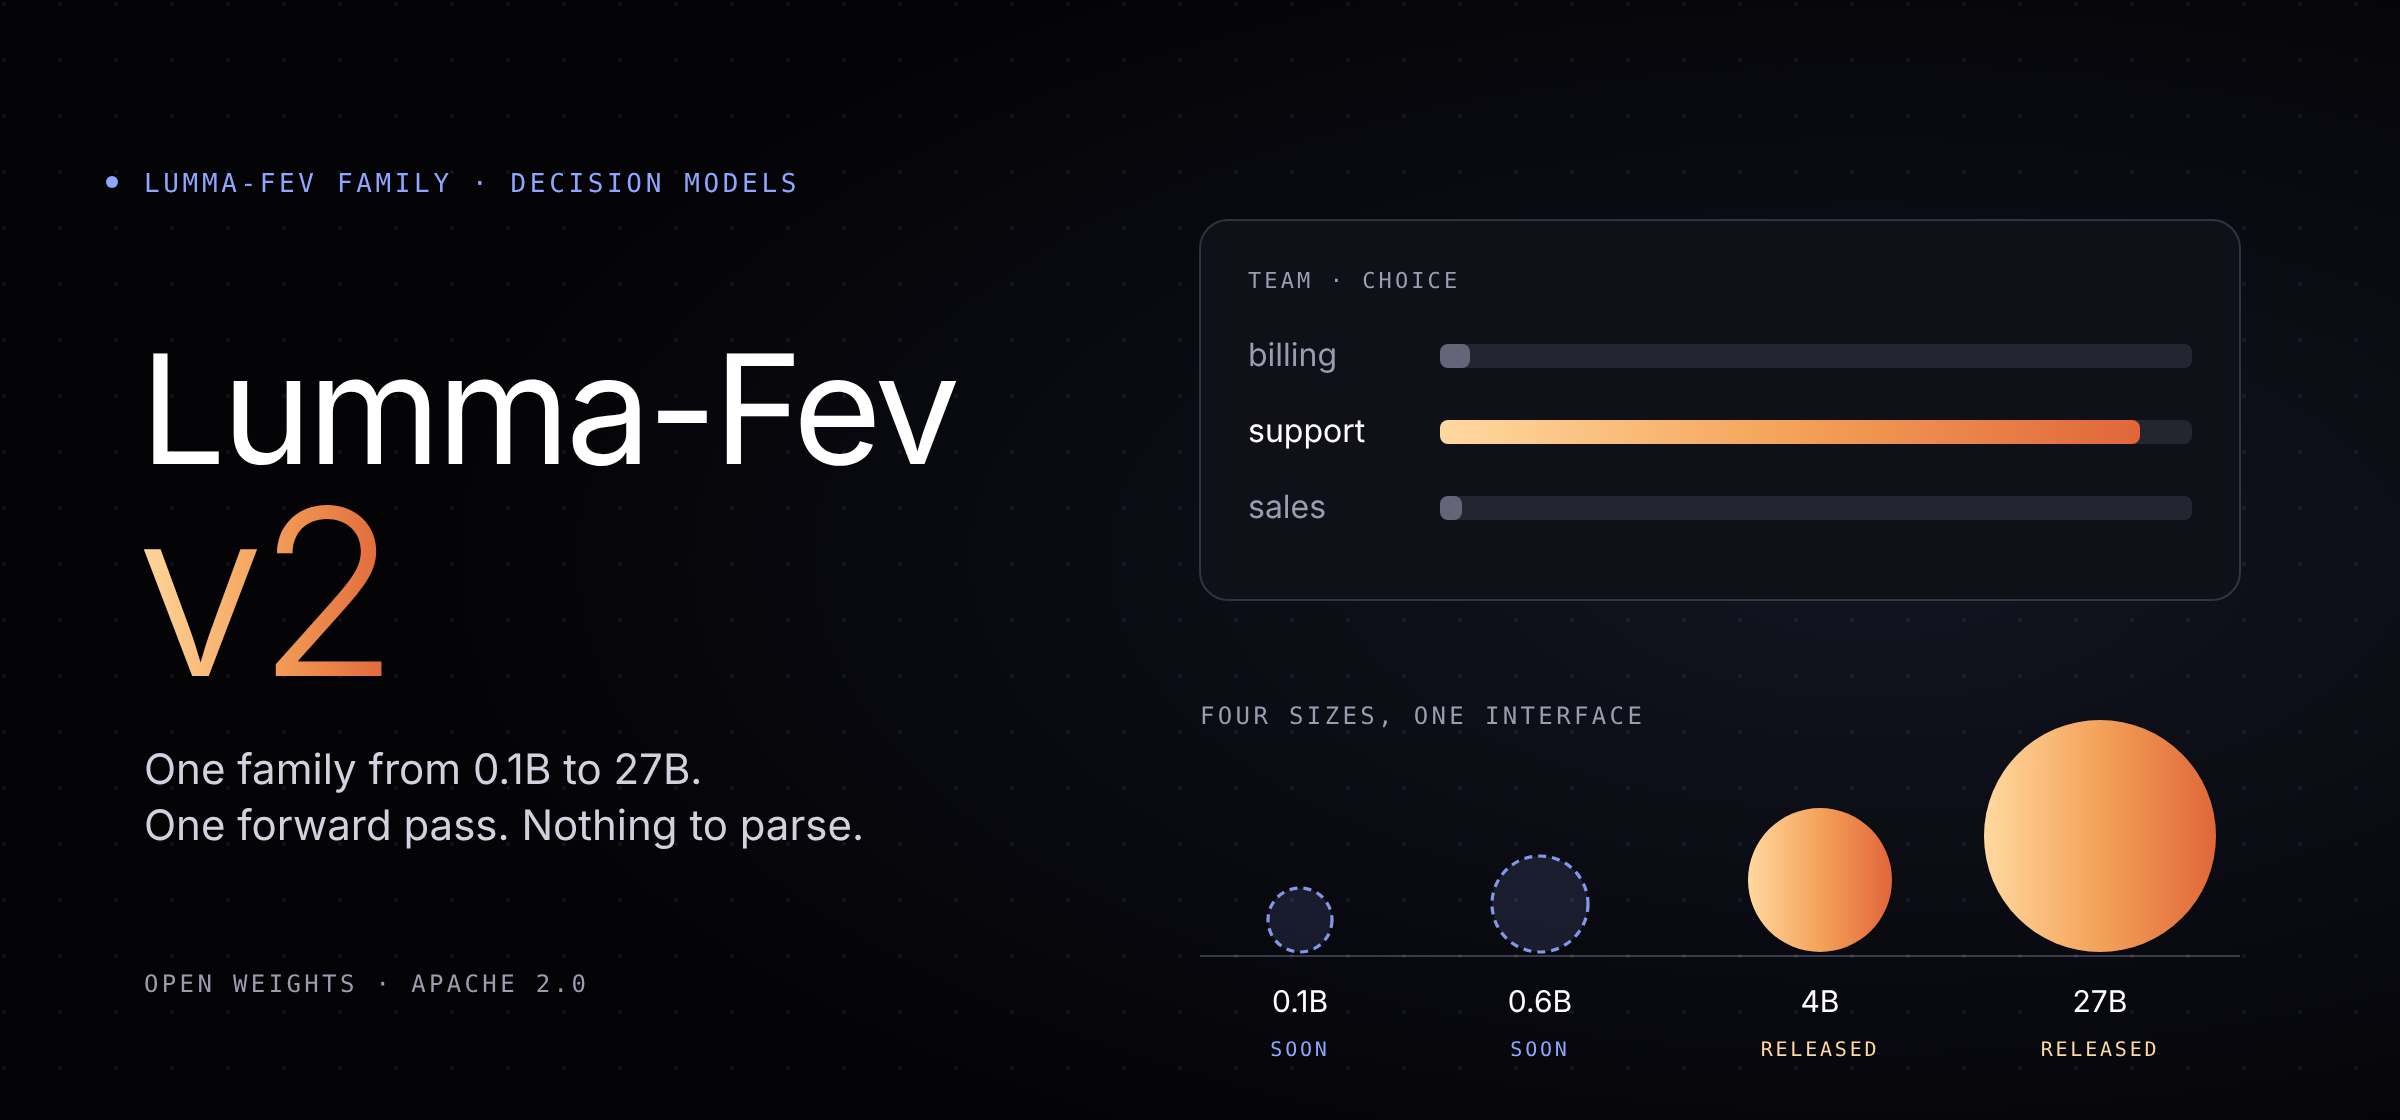
Introducing Lumma-Fev-v2
The second generation of our decision models: 4B and 27B released, ahead of Jev on average and better calibrated.
Read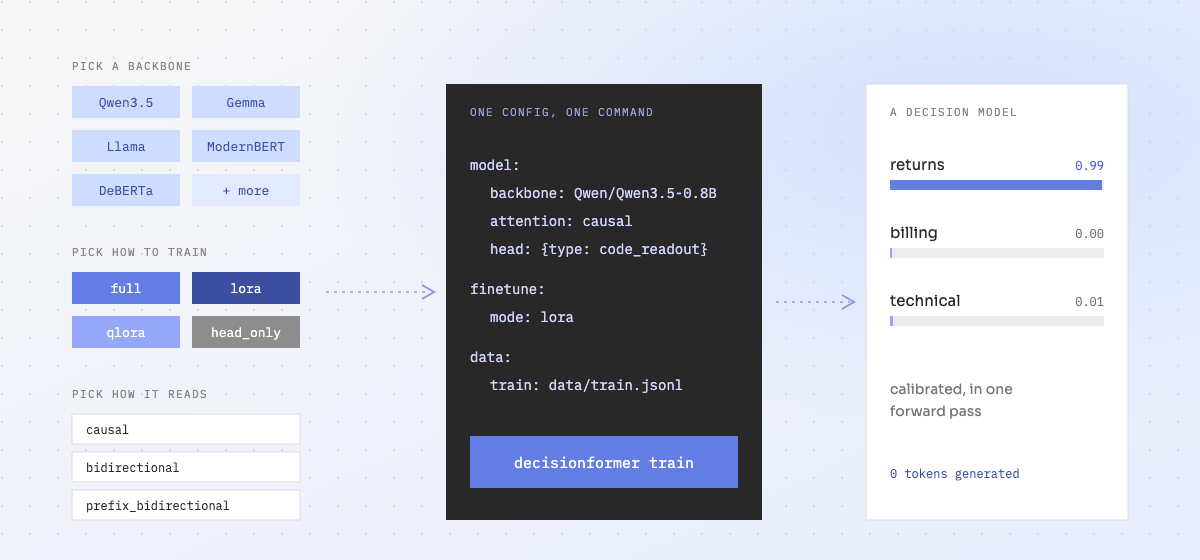
DecisionFormer
Fine-tune any Hugging Face model into a one-pass decision model, with full fine-tuning, LoRA or QLoRA.
Read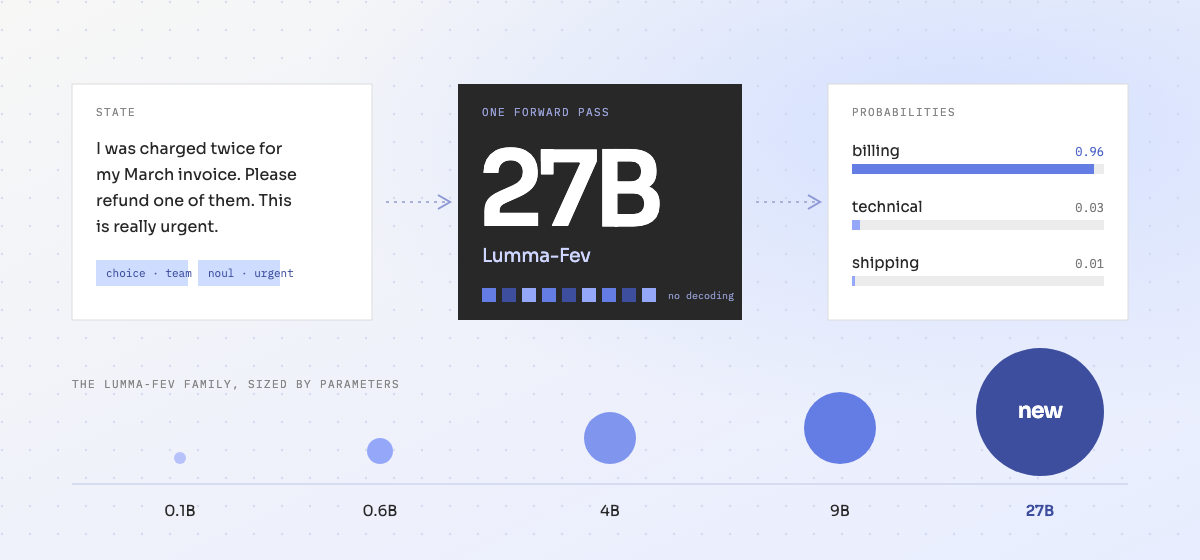
Introducing Lumma-Fev-27B
Our largest decision model, trained on about 100K samples, and how it compares with Jev.
Read
Introducing Lumma-Fev
Our decision model that scores your options in one pass.
Read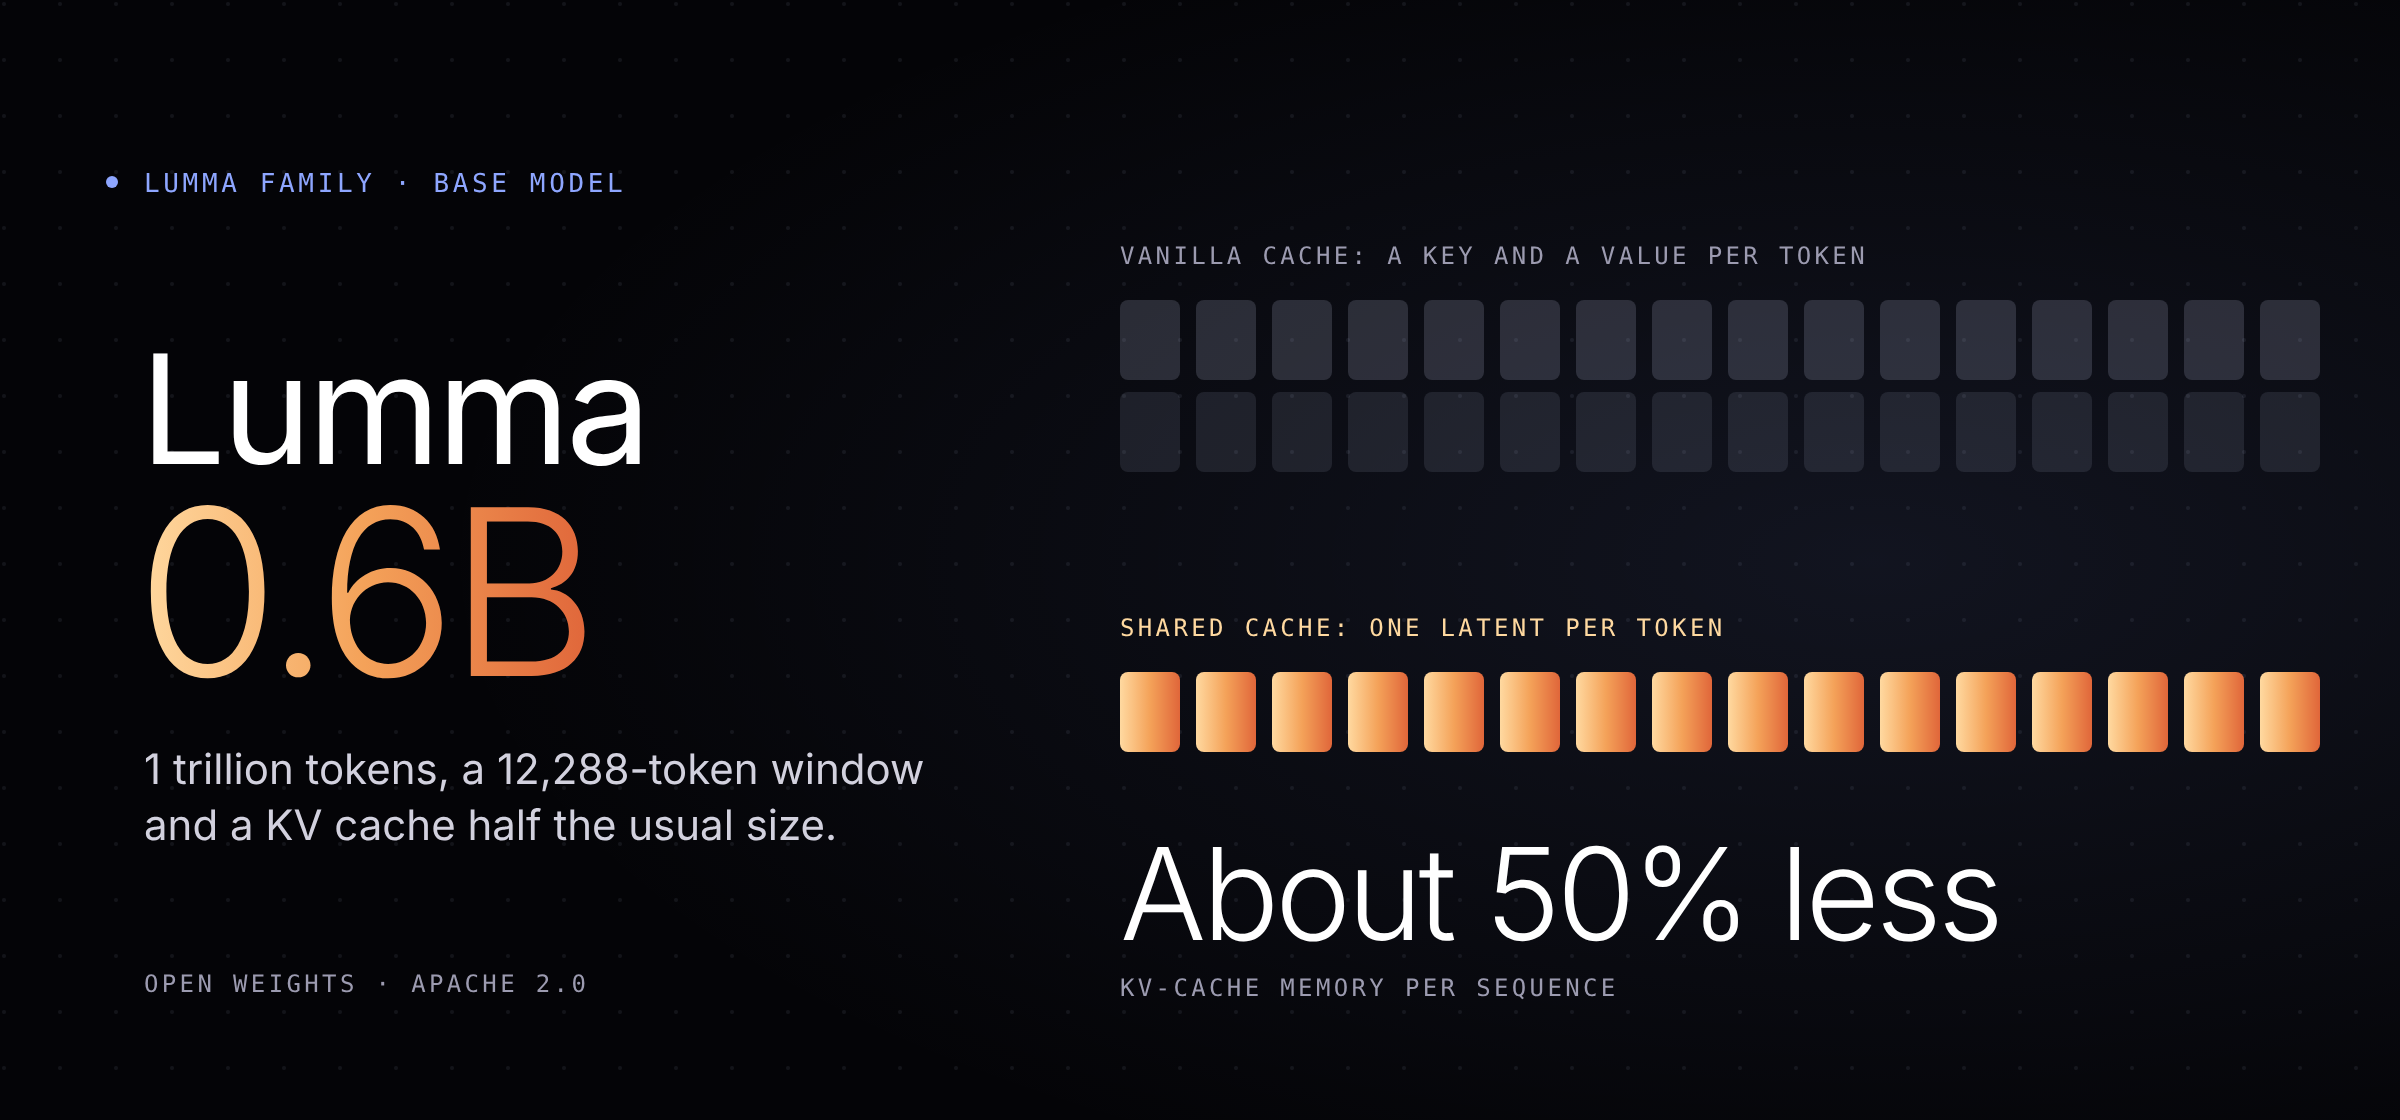
Introducing Lumma-0.6B
A 0.6B foundation model with a 12,288-token window and a shared KV cache half the usual size.
Read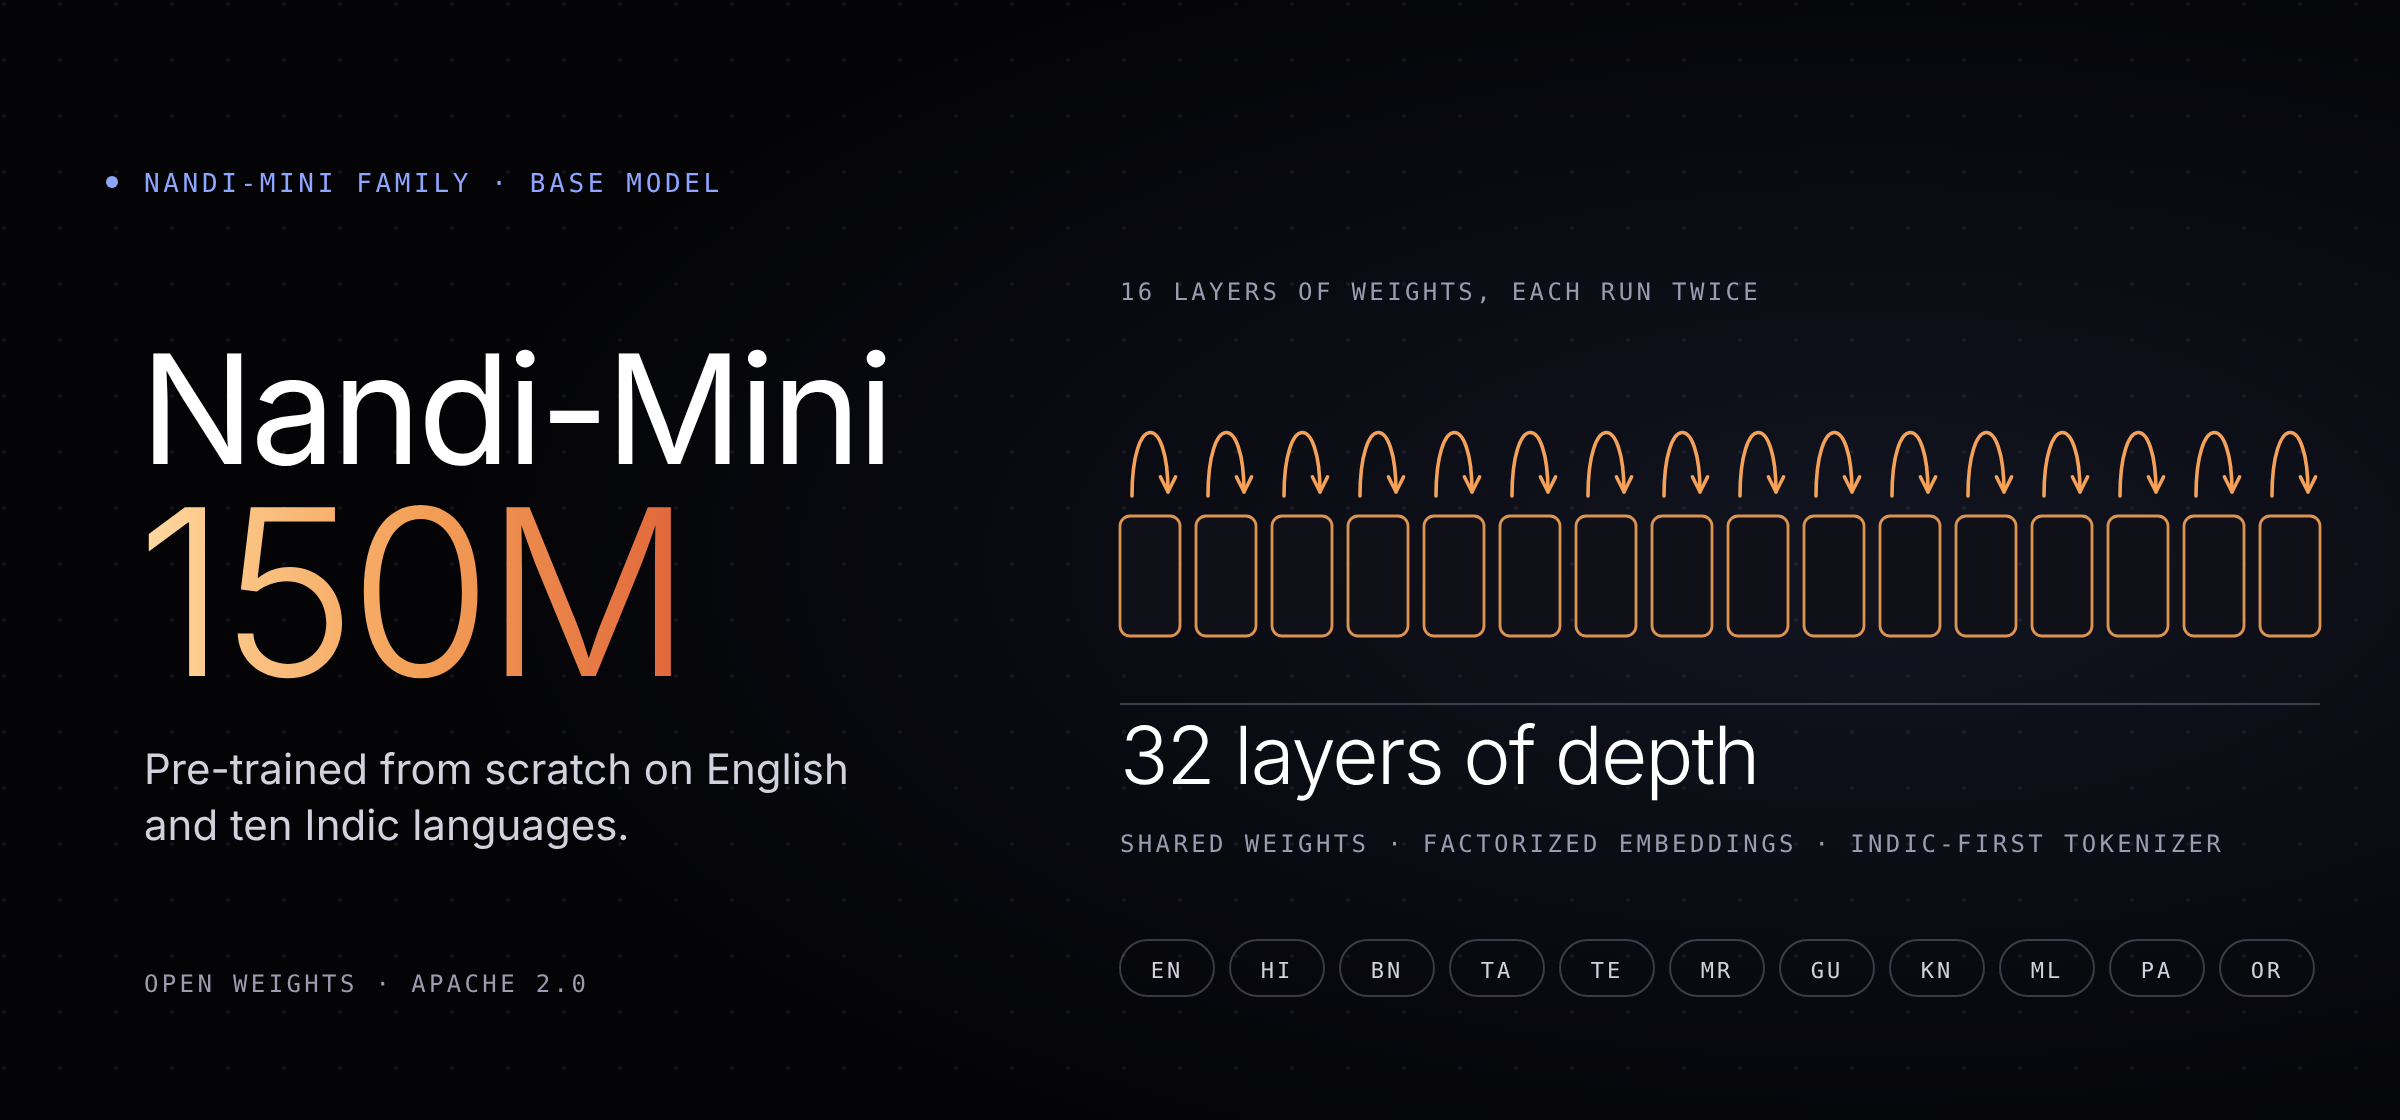
Introducing Nandi-Mini-150M
A 150M foundation model for English and ten Indic languages: sixteen shared layers, thirty-two layers of depth.
Read